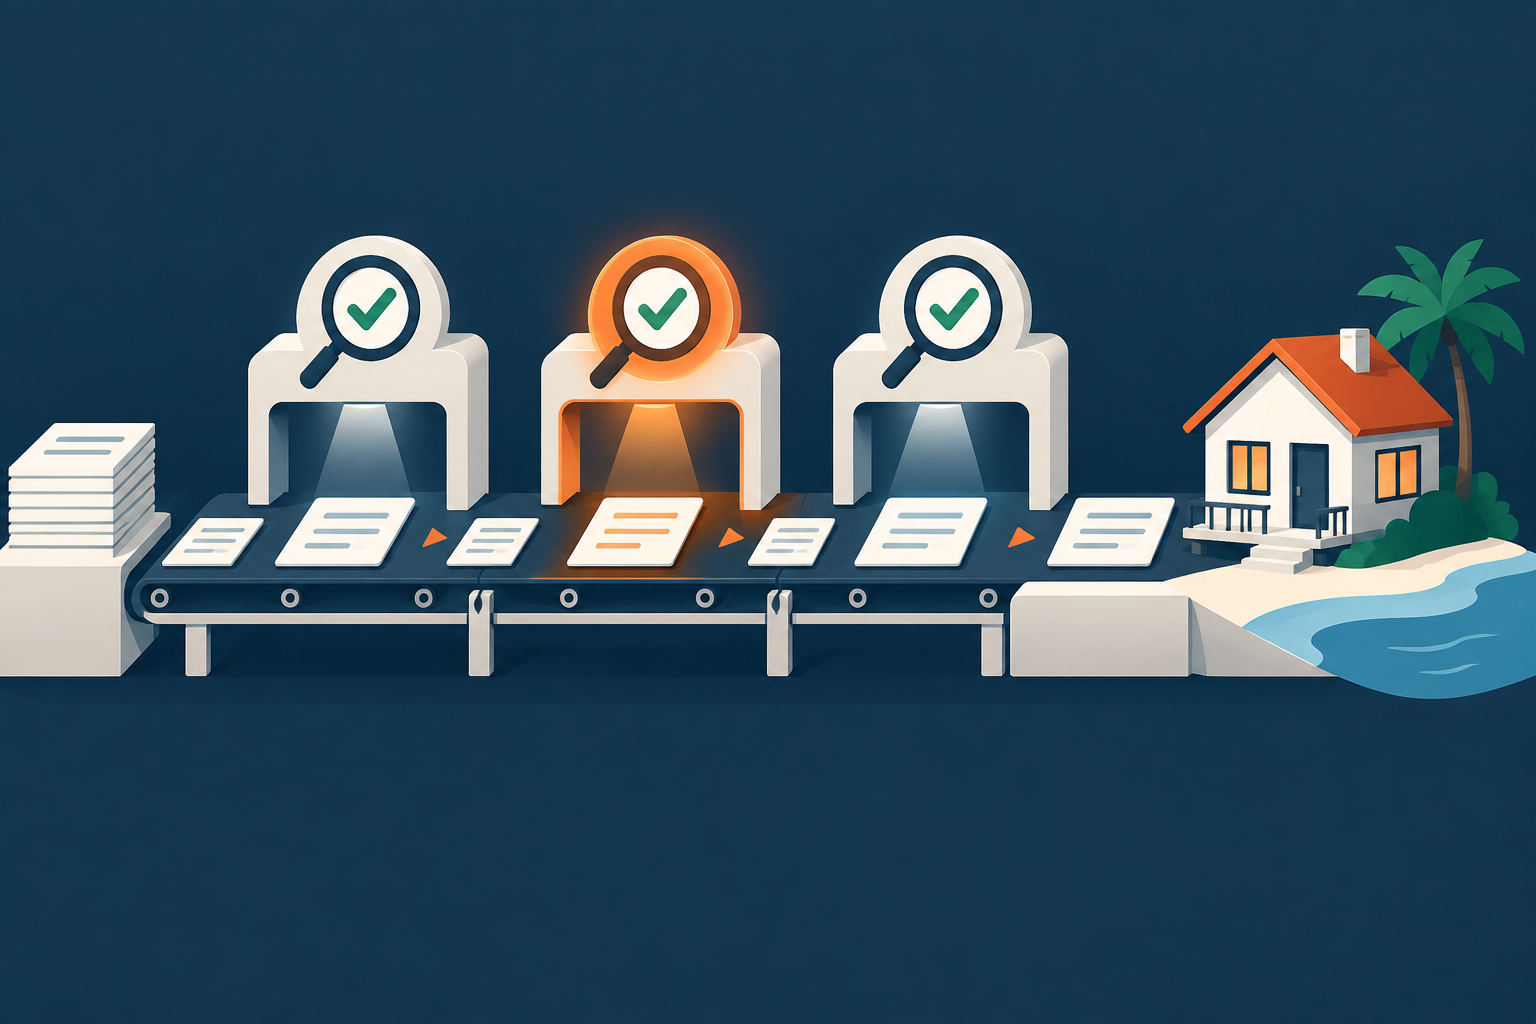
I almost gave up on AI because I asked one prompt to do six jobs at once, and it handed back a client plan built on "close enough" data instead of the real numbers. What changed my mind was a lesson from manufacturing: I split that one request into 6 separate components, put a quality-control check between each one, and the same tools started producing work I could put my name on.
This is the story of that failure, what I rebuilt, and the process I now teach STR operators who are ready to quit on AI for the same reason I almost did.
Last updated: September 2026
What Went Wrong When I Tried to One-Shot the Project
A client came to me needing a consulting-grade deliverable. The scope was large. I wanted AI to analyze the client's profile, research their location, generate 5 high-value customer avatars, organize 91 STR development projects, complete a resource analysis, and assemble a full business plan. All at once. In one prompt.
I had a reason to push. What I estimated a big-firm engagement would cost for that scope was somewhere between $32,000 and $75,000. That is my own estimate of what a large consulting firm would bill, not a quote anyone gave me. My back was against the wall competing with firms that size, and I thought automation was the way to close the gap in one move.
It did not work. Here is what broke:
The context window gave out. The model could not hold the client profile, the market research, the avatar logic, and 91 projects in view at the same time. Details from the start of the conversation stopped showing up in the later sections.
Data got "helpfully" shortened. Market figures I had supplied came back rounded, trimmed, or swapped for numbers the model thought were close enough.
Long requests hung. Complex multi-step requests would stall partway through, and I had to restart and lose hours of work.
Assumptions replaced questions. Instead of asking me for missing information, the model made up customer demographics, market conditions, and project timelines. Garbage in, disaster out.
The output looked professional. That was the dangerous part. It read like a finished plan, and if I had not checked it line by line against my source material, I would have sent a client a document with invented numbers in it.
Why the Model Filled Gaps With "Close Enough" Data
I blamed the tool at first. Later I understood I had asked it to do something it is not built to do well.
Anthropic's documentation describes the context window as the model's "working memory," separate from the data it was trained on. The same page says that as the token count grows, accuracy and recall degrade, which it calls "context rot." That matched what I saw. The more I stuffed into one request, the less reliably the model remembered what I had told it at the top.
The second problem is how these models respond to gaps. When a language model does not have a fact, it tends to produce something plausible rather than stop and say "I don't know." In a blog draft, that is annoying. In a market analysis or a guest message about a refund, it is a liability.
Anthropic's prompt-engineering guidance points the same direction: give the model clear instructions, supply the reference material it should rely on, and break complex tasks into simpler subtasks. Anthropic's guide calls this chaining prompts, where the output of one step becomes the input for the next. I had done the opposite. I had built one giant step with no checkpoints.
There is also a regulatory angle STR operators should not ignore. The Federal Trade Commission enforces federal consumer protection law against deceptive business practices, and it keeps a dedicated page on artificial intelligence as part of that work. Using software to write a claim does not change who made it. If an AI tool writes a listing that says "5 minutes to the beach" and it is 20, that is your claim, not the software's.
The Manufacturing Lesson: Quality-Control Stations
Then it hit me like a factory floor accident. I was trying to run a complex assembly line at 10 times normal speed with no quality-control stations.
No manufacturer builds a car by dumping every part into one machine and hoping a finished vehicle comes out. They build components. Each component gets inspected before it moves to the next station. If a bad part gets caught at station 2, you lose one part. If it gets caught at final assembly, you lose the whole car.
AI work behaves the same way. An error in the first step, like a wrong occupancy figure or a misread address, carries into every step after it. By the time it reaches the finished document, it is buried under pages of confident writing that depend on it.
The NIST AI Risk Management Framework, a voluntary framework from the National Institute of Standards and Technology, organizes AI risk work around four functions: Govern, Map, Measure, and Manage. You do not need to adopt a federal framework to run a short-term rental. The useful idea for an operator is simple: decide who is responsible, know where the tool can fail, check the output against something real, and act on what you find. A quality-control station is that idea on a small scale.
The Six-Component Rebuild
I redesigned the whole project using manufacturing principles. One request became 6 components, each with its own inputs, its own rules, and a check before the next one started.
Component 1: Customer Profile Analysis
The model analyzes only the client information I provide. No substitutions are allowed. I tell it in writing that if a field is missing, it must list the gap instead of filling it. I verify the summary against the intake before moving on.
Component 2: Location Research
This runs as a separate conversation using the verified location from Component 1. It covers the market, the regulatory environment, and competition. Every regulatory point gets checked against the city or county source, because this is where models are most likely to state something outdated with confidence.
Component 3: Avatar Generation
The 5 customer avatars are built only from the validated profile and location data. No "likely" demographic characteristics get added without a reason I can trace. Each avatar is tested against actual market data from Component 2.
Component 4: Project Organization
The 91 development projects were the biggest single reason the original run failed. So I stopped asking for all 91 at once. I split them into smaller batches, categorized each batch by priority and resource requirements, and checked every batch before starting the next. Then I ran one final pass to sequence the categorized list and build a timeline.
Component 5: Resource Analysis
This step pulls only from verified components. It looks at the resources the prioritized projects need, identifies gaps, and lays out return projections for each phase. I check every projection's math by hand or in a spreadsheet, because the model is better at describing a calculation than doing it reliably.
Component 6: Document Assembly
The final step compiles the approved components into the business plan and cross-references the numbers for consistency. The rule here is that assembly adds no new facts. If a figure appears in the final plan, it has to appear in a checked component first.
With that structure, the deliverable I had estimated at $32,000 to $75,000 from a big firm became something my team could produce with checked data. AI carried the volume. People checked each station.
The Process: Breaking Any AI Task Into Checked Stages
You do not need a 91-project consulting job to use this. The same process works for a guest message, a listing rewrite, or a market check. Here is the version I teach operators:
Write the finished result in one sentence. For example: "A reply to a guest asking for early check-in that matches our house rules and cleaning schedule." If you cannot describe the result in one sentence, the task is too big for one stage.
List the source material the AI must use. House rules, your cleaning calendar, your listing text, your own booking data. Paste or attach it. Do not let the model rely on what it thinks a typical host does.
Split the task into 3 components or fewer for your first attempt. A listing rewrite might be: pull the facts, draft the copy, check the draft against the facts. Keep each component small enough that you could check its output in about 5 minutes.
Add a "no substitutions" instruction to every component. Tell the model in plain words: do not change numbers, do not add amenities, do not estimate missing data, and list anything you could not find.
Run component 1 by itself and check it. Compare the output against your source material line by line. Do not move on until it passes.
Feed only the approved output into the next component. Start a fresh conversation or clearly paste in the approved result, so older, unchecked drafts are not sitting in the context window.
Put a human check before anything goes to a guest, a platform, or a client. This is the final quality-control station. Nothing leaves the building without it.
Log what failed and change the instruction, not only the output. If the model keeps rounding cleaning fees, add a rule about it to the component prompt. Fix the station so the next part comes out right.
Start with 3 components, not 6. My first rebuild used 6 because the project demanded it, but most operator tasks need 2 or 3.
Where This Fits in an STR Operation
The table below maps common STR tasks to the stage where AI does the work and the human check that has to happen before the output is used. The thresholds come from the process above and from Airbnb's own Superhost requirements, which include responding to 90% of new messages within 24 hours and keeping a cancellation rate under 1%.
STR task | AI stage | Human QC check | Why the check matters |
|---|
Guest messaging drafts | Draft the reply from your house rules and the guest's message | Confirm every date, time, fee, and policy against the reservation before sending | Superhost requires responding to 90% of new messages within 24 hours, so speed counts, but a wrong promise costs more than a slow reply |
Listing copy | Rewrite the description using only your amenity list and photos | Check each amenity, distance, and bed count against the property | The FTC polices deceptive business practices, and a wrong listing claim is yours even if AI wrote it |
Market research | Summarize comparable listings and local rules you supply | Verify every rule against the city or county source | Regulatory details are where models most often state outdated facts |
Pricing review | Flag nights where your rate sits far from your own history | Approve changes in your pricing tool yourself; spot-check 5 nights by hand | A pricing error repeats across every booked night until someone catches it |
Cancellation or refund replies | Draft a response citing your stated policy | Read the reservation's actual policy before sending | Superhost requires a cancellation rate under 1%, and a careless reply can create one |
Notice that the AI stage never includes the final decision. It drafts, sorts, and flags. People approve.
Failure Modes and Fixes
Every failure I hit on the 91-project job shows up again in smaller form in day-to-day STR work. This second table lists the failure modes I see most often when operators tell me AI "doesn't work," with the symptom you will notice and the fix that follows from the process.
Failure mode | Symptom you will notice | Fix |
|---|
Context overload | Later sections forget details from the start, like 91 projects collapsing into a vague summary | Split into smaller batches and check each one |
"Close enough" substitution | Numbers come back rounded or slightly different from what you supplied | Add a "no substitutions" rule and compare output to source line by line |
Invented facts | Amenities, distances, or local rules appear that you never provided | Supply the source material and require the model to list what it could not find |
Stale draft contamination | Old versions of a message or listing leak into new output | Start a fresh conversation for each component and paste in only approved output |
Hung or failed long runs | The tool stalls partway and you lose the session | Keep each component small enough to check in about 5 minutes |
No final check | A confident but wrong message reaches a guest or client | Make a human review the last station before anything is sent or published |
If you have given up on AI because it keeps substituting data, I understand. I almost did too. My problem was asking one step to do the work of six.
Start Small This Week
Pick one manual task you do every week, such as a guest message type, a listing update, or a market check. Break it into 3 components. Run and check component 1 only. Write down what the model changed or invented, then add a rule to stop it.
If you want help mapping where AI fits in your operation and where the quality-control stations belong, book a complimentary one-on-one diagnostic call. The diagnostic is free. If it makes sense afterward, the $997 action plan turns what we find into a written build order for your business.
Frequently Asked Questions
Why does AI give wrong numbers even when I provide the data?
Long requests push the model past what it can reliably track, and Anthropic's documentation notes that accuracy and recall degrade as the context grows. The model may also round or swap figures it treats as close enough. Break the task into smaller components and tell it explicitly not to change any numbers.
How many components should I start with?
Start with 3 or fewer. My consulting project needed 6 because it covered a client profile, location research, 5 avatars, 91 projects, a resource analysis, and a business plan. Most STR tasks, like a guest reply or a listing rewrite, work well in 2 or 3 stages.
Can I let AI send guest messages automatically?
I do not recommend sending AI drafts without a human check. Airbnb's Superhost standard asks you to respond to 90% of new messages within 24 hours, which leaves time to review a draft. A wrong date, fee, or policy promise creates a bigger problem than a reply that took a few extra minutes.
What is a quality-control station in an AI workflow?
It is a checkpoint between stages where a person compares the AI output against source material before it moves forward. In manufacturing, a defect caught early costs one part instead of a whole product. The same logic applies to a market analysis or a listing.
Is AI-written listing copy my responsibility?
Yes. The FTC enforces federal law against deceptive business practices and tracks AI as a focus area, and a listing is your claim no matter who drafted it. Check every amenity, distance, and bed count against the actual property before publishing.
Did the manufacturing approach replace consultants for you?
It let my team produce a deliverable I had estimated a big-firm engagement would charge $32,000 to $75,000 for, with data we checked at each stage. AI handled the volume, and people checked each station.
Sources
Keep Reading